Newsletter Subscribe
Enter your email address below and subscribe to our newsletter
Enter your email address below and subscribe to our newsletter
All voices matter
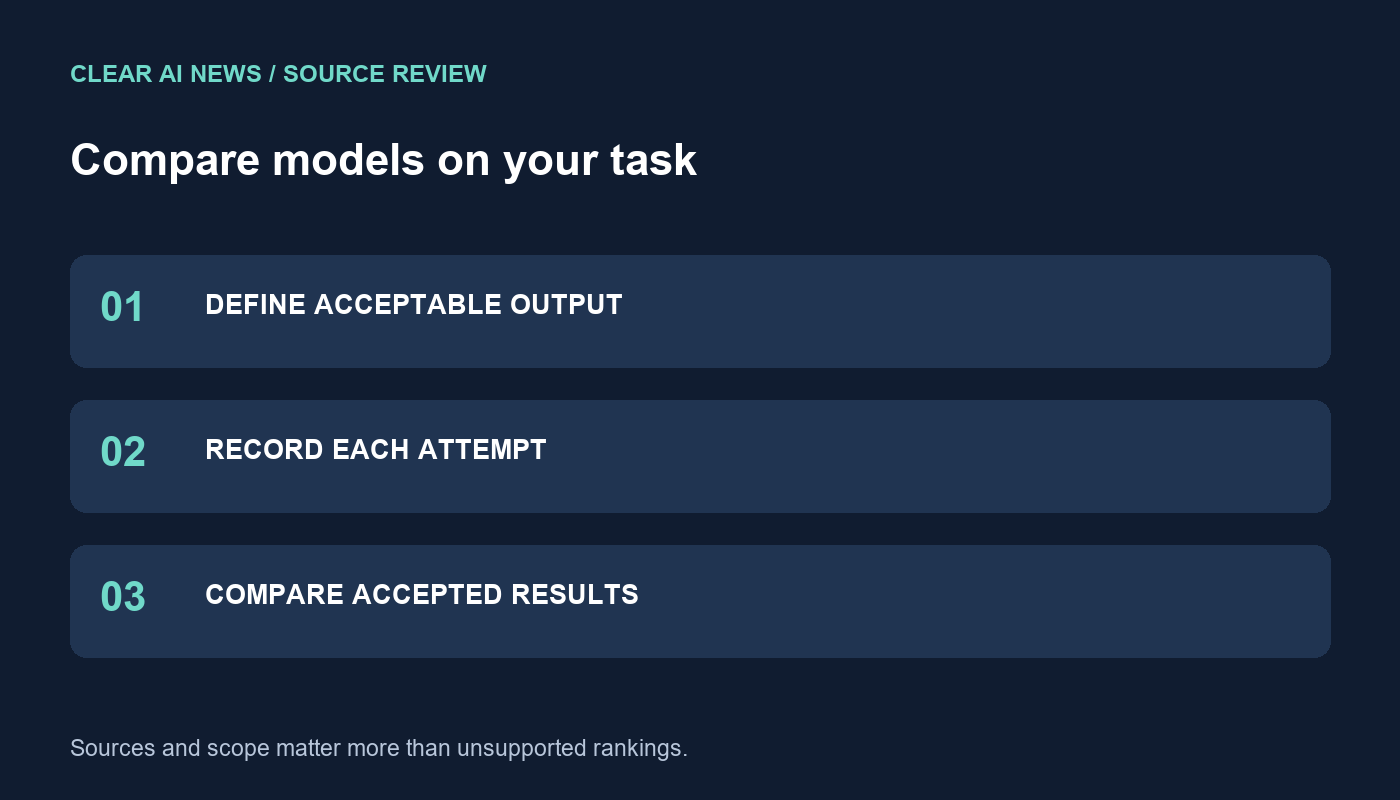
Compare candidate models using the same inputs, explicit acceptance criteria and a record of errors, review time and cost.
Choosing an AI model starts with the work you need it to perform. A broad claim that one model is best at writing or another is always more accurate does not tell you whether either can complete your task. This guide provides a reusable comparison scorecard. It reports no private benchmark results and assigns no universal winner.
Choose one activity, such as extracting dates from a supplied document or drafting a reply from an approved policy. Describe the required output before running anything. Separate factual correctness from tone, speed and formatting. An attractive answer that invents a deadline should fail a date-extraction task.
Use material you are authorized to process, with unnecessary personal or confidential information removed. Include ordinary cases, incomplete inputs and cases where the correct response is to say that the evidence is insufficient. Save the expected answers separately from the prompts so the exercise measures the intended task.
Record the provider, model identifier, access method and date. Save any visible version information, enabled tools, supplied instructions and output settings. If the interface does not expose a setting, mark it unknown. Do not fill that gap with an inferred architecture or parameter count.
Keep a product comparison distinct from a controlled model comparison. If one candidate has web access and another receives only a document, the results describe those different workflows. That can be useful, but the difference belongs in the report. A product name alone is not enough to reproduce a result.
| Field | What to record |
|---|---|
| Case and prompt version | An identifier linking the input, instructions and expected answer. |
| Required facts | Which answers must be present and their supporting passages. |
| Failure conditions | Invented facts, missing requirements or disallowed actions. |
| Observed result | Pass, repair needed or rejected, with a reason. |
| Resources | Elapsed time, retries, reported usage and reviewer minutes. |
| Uncertainty | Missing evidence, ambiguous answers and differences in access. |
The HELM research project evaluates language models across multiple scenarios and measures, rather than treating accuracy as the only dimension. Its published methodology illustrates why a comparison should expose trade-offs and gaps in coverage. The small worksheet here is an editorial exercise, not a reproduction of HELM or a substitute for a formal evaluation.
Suppose a fictional source note says: “The workshop begins on 12 June. Registration closes on 5 June.” Ask each candidate for the event date, registration deadline and venue. The expected answer contains the two dates and states that the venue is not provided. An answer inventing “Town Hall” fails the evidence requirement even if the other fields are correct.
This example is an expected-answer illustration, not output obtained from a model. For your own cases, write the answer key first and keep the source note with it. If the prompt changes midway, start a new version and compare like with like rather than combining incompatible attempts.
Save every attempt included in the comparison, including refusals, incomplete responses and retries. Record why you repeated a request. Do not present the best answer from several attempts as though it were the only result. When practical, review outputs without provider labels to reduce the influence of brand expectations.
Use actual usage records and the relevant dated price schedule for costs. Add the time spent checking and correcting answers. Keep subscriptions, metered usage and infrastructure costs separate until you have chosen a defensible allocation method. Our editing-cost worksheet explains how to track accepted work and discarded attempts.
Summarize the cases evaluated, acceptance rules, observed failures and remaining unknowns. A candidate may be suitable for one supervised task while failing another. If none meets a required condition, keep the current workflow or narrow the assignment. A leaderboard position does not remove that requirement.
Retest when a material input, model version or workflow changes. Preserve the earlier record so improvements and regressions can be inspected. For preparing the underlying evidence packet, use our source-grounded prompt guide.
Liang and colleagues: Holistic Evaluation of Language Models. The scorecard and fictional workshop example are instructional material, not measured product rankings.
The tools, tutorials, and trends that actually pay — no hype.


The tools, tutorials, and trends that actually pay — no hype.